AI visibility · Türkiye
How does AI describe you?
See what to change.
Examine where your brand stands in search and AI answers. See the sources, choose the priority actions, share the results with their evidence.
No signup · no card · a technical readiness check
Request a quote1
Measure
The registered question plan is measured on the engines in its scope; answers obtained and results that could not be measured are recorded apart.
2
Inspect
Who is named, which source was read, why your name is missing — the evidence is one click away.
3
Act
Pick the priority action, record the change; the next measurement shows the movement with its evidence.
Which brand would you recommend in this category?
Illustrative answer — not a measurement; designed to show the interface.
Measured across five answer engines
Turkey data
Who writes the Turkish answers?
Measured from our own scans: 16 brands, 61 runs, 75,417 citations. This is our client portfolio, not a market sample; the numbers belong to that date and that portfolio.
Şikayetvar
The single most-cited source in AI answers about Turkish brands. It appears across all five engines.
Most citations are not your site
Only 6.4% of the sources behind those answers are the brand's own domain. Fixing your own site is necessary and not sufficient.
Sources that carry reviews
Şikayetvar, Trendyol, Hepsiburada, Akakçe: when these are cited, negative framing runs 3.6× the baseline — and positive rises too. Reviews displace neutral.
Read, but not credited
An engine can cite your site and never say your name. 3 answers in 100 on ChatGPT, 26 on Claude. That is an attribution problem, not invisibility.
Measured 3 August 2026. A citation is not what that source said about you; we measured which source was read.
Not a list. One answer.
Search offered a list of options; AI gives a single recommendation. If your name is not in that sentence, you are not even a candidate to compare.
The product loop
One fictional brand, start to finish.
How a measurement's scope is registered, what the evidence looks like, how a finding becomes an action, and what the next measurement says. The numbers below are the shapes the product shows, not a customer result.
Fictional sample: Example Brand is not a real customer; no number here is a measurement result.
1 / 5
Scope
What will be measured is registered first.
For Example Brand, three personas, four intents and two answer engines are registered. The plan is frozen; no question is added or removed afterwards. Each cell is one persona, one intent, one engine.
- 3 personas
- 4 intents
- 2 engines
- 24 cells
2 / 5
Evidence
Answers obtained and answers not obtained are written apart.
Twenty-two of the twenty-four cells return an answer; two do not, and that is recorded. An answer that could not be obtained is never read as "you were not mentioned"; it leaves the denominator.
22 / 24cells answeredmeasured
2 cells unmeasured · recorded, outside the denominator
3 / 5
Finding
A measured absence is a finding.
None of the eleven answers under purchase intent mentions Example Brand. That is not missing data but a measured result; the answer text and its sources are one click away.
0 / 11answers mention it · purchase intentmeasured · no mention
evidence: answer text and cited sources, cell by cell
4 / 5
Action
A suggestion becomes an action through a human decision.
The engine suggests an action; the team plans it in the Action Center, produces the content and declares it published. The declaration date is the clock of the later comparison.
- Suggested
- Planned
- In progress
- Published (declared)
each step records who, when and why
5 / 5
Comparison
The next measurement states the outcome, not the page.
When a second measurement is published under the same registered plan, the windows before and after the publication declaration are compared. One of four outcomes results, written under its own name.
Awaiting re-measurement
no second measurement yet
Changed
the registered pair moved
Unchanged
the registered pair stayed
Incomparable
the plan or the denominator changed
A completion mark is not an outcome; an outcome comes only from the comparator.
Today and the vision
What it does, and what it does not yet claim.
The dashboard and the research brief use the same language as this page: what is done under its own name, and what is not yet qualified under its own name.
Today
Measurement and findings
A registered question plan is measured across the engines in its scope; answers obtained are kept as evidence, answers not obtained are written apart. Every number comes with its denominator.
Actions and follow-up
Decisions are recorded, publication is declared, the next measurement is compared over before and after windows. Changed, unchanged, incomparable: all three are valid outcomes.
Behaviour analysis
Patterns in observed AI answers: in which questions and contexts you are mentioned, and in which you are measurably not. It is not a claim about what people do.
Controlled scenarios
Model answers under declared inputs: what was varied and what was held fixed is registered. Today this produces engineering evidence with a fake provider; real acquisition needs its own authorization.
Vision, conditional
Representation of human behaviour
The claim that personas represent a real population is not made without independent behavioural evidence for that population. A plausible synthetic persona does not establish it on its own.
Forecasting
A forecasting foundation exists and abstains: no forecast is produced before an admissible history, a versioned procedure and a declared empirical gate are in place.
That a capability is implemented does not mean it is validated. The dashboard keeps that distinction on every surface.
Platform
Measure it, explain it, fix it.
Five modules, one console. Every number shows how it was calculated — no black-box scores.
Visibility Measurement
Share of voice, sentiment and citation sources across five engines. See who gets recommended, question by question.
ExplorePersona Intelligence
Questions come from real buyer motivations, not keywords: Censydiam, archetypes and Turkey-specific persona sets.
Explore- Security
- Belonging
- Enjoyment
- Control
Ad Intelligence
What ads your rivals run, placed beside their visibility in AI answers. It makes no claim that ad spend produces visibility; the two are separate measurements.
Explorea 61-point gap
Fact Check
Finds the false claims AI makes about your brand — and their sources, so you know what to correct.
Explore- “Founded in 2019”false
- “Headquartered in Ankara”false
- “ISO 27001 certified”true
Agency Console
Dozens of clients in one console with separate permissions. No separate contract per client.
ExploreFree
Your site's AI-readiness report
No signup, no card. Technical access, content, structured data and E-E-A-T checks, plus a first look at what AI says about your brand.
Check technical readiness- AI access
- Citation sources
- Content depth
- Brand accuracy
68%
of Google searches in the US ended without a click, early 2026.
SparkToro / Similarweb, US, Jan–Apr 2026up to +40%
measured by KDD 2024, in its own benchmark, from adding statistics and quotations to sources already in the answer — a hypothesis to test, not a promise.
Aggarwal et al., KDD 2024 (arXiv:2311.09735)93.6%
of the citations behind AI answers came from somewhere other than the brand's own domain, in our own client portfolio.
Our own scans, 16 brands, 61 runs, 3 August 20265
answer engines in a registered measurement: ChatGPT · Gemini · Perplexity · Claude · Google AI Overview.
What GoPersona measuresMethod
Everyone says “persona analysis”. Ours you can inspect.
The wheel below is not an illustration: it reads the same data the product does. Click a motivation and watch the questions change.
Security
Security
Taking no risk, wanting a guarantee, being at ease.
Questions this motivation produces
- “{marka} güvenilir mi, garantisi var mı?”
- “{marka} ile çalışırken risk var mı?”
- “{kategori} alırken nelere dikkat etmeliyim?”
Absent here: An audience looking for reassurance does not come back if it sees a negative source in the answer. If you are not writing the answer to this question, someone else is.
Motivation
8 motivations
Security asks for guarantees, Recognition asks which is best, Belonging asks what everyone uses. Same buyer, three different questions — and a brand can be present in one and absent in the others.
Inspect →Audience
16 personas, from national data
Not invented. Each carries the measurement it came from: 19.2% individual AI use, 97.7% of firms are SMEs, half of e-commerce volume is aged 25-36.
Inspect →Foundation
52 checks, 14 critical
All published and downloadable. Usable without our tool: hiding the list is worth less than giving it away.
Inspect →Measured on our own brands
Being mentioned is not enough. Do they mean you?
GoPeople was named in all three answers, and all three cited gopeople.com.au. The answers described a courier company on another continent. Every mention-counting tool scores that as a success.
GoPeople: the share of what engines say that its own pages account for. The rest is a different company with the same name.
GoVista: the same measure. The remainder holds Samsung MagicInfo, a real rival its own site never names.
No signup, no card. Shows what the engine actually says.
The evolution of visibility
From the first computer to answer engines: an eighty-year story with one rule that changes in every era — the visible one wins. Scroll: time is yours.
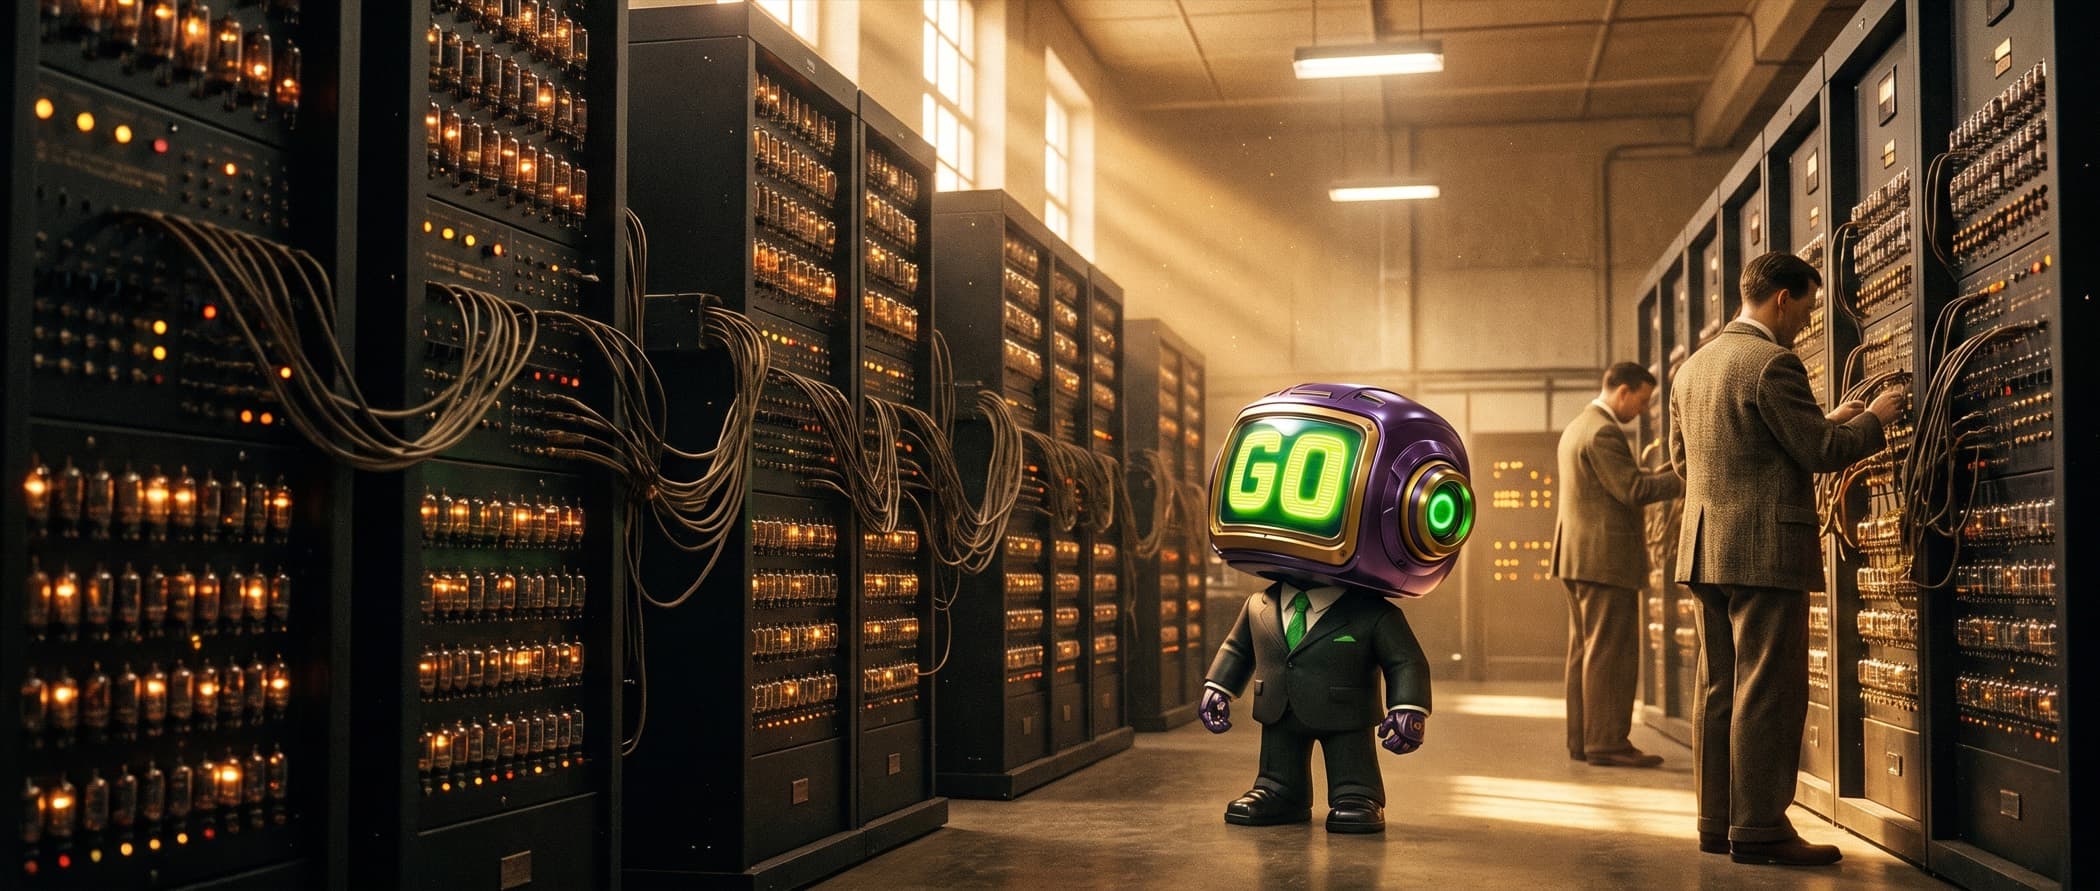
A thirty-ton brain woke up.
ENIAC: 27 tons, 17,468 vacuum tubes, a whole hall. Information became the work of machines, but only a handful of scientists could reach it. Visibility was not yet anyone's worry.